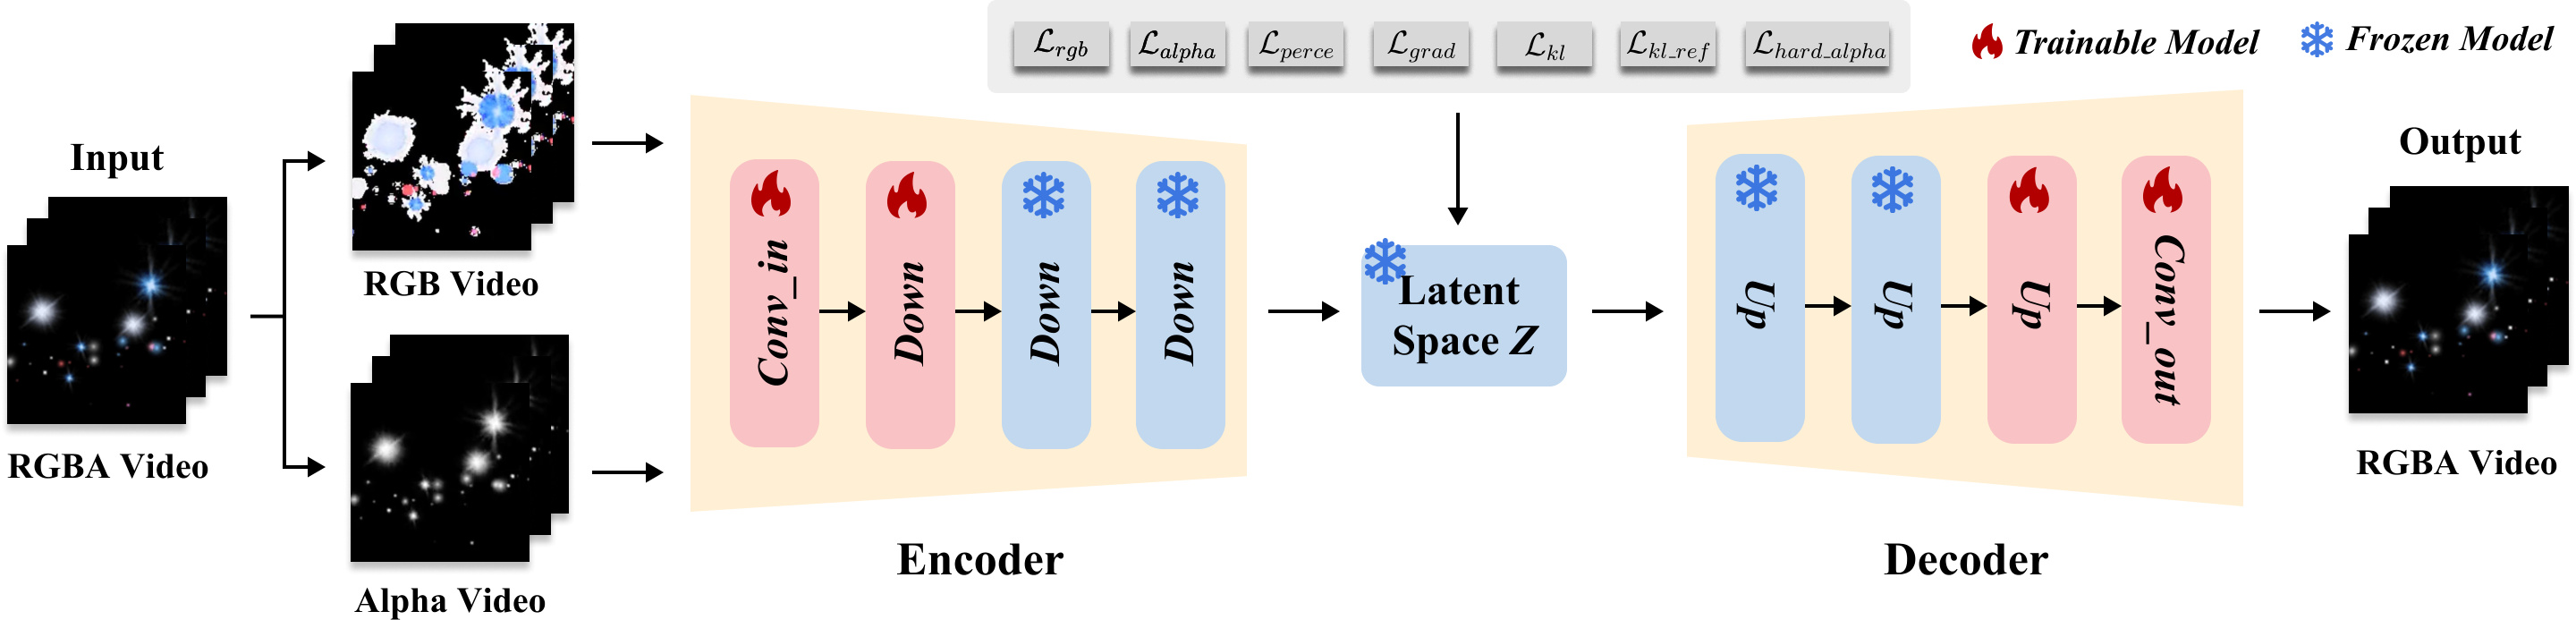
A unified framework that extends a causal video VAE to four-channel RGBA via zero-initialized channel expansion and selective layer unfreezing. Standard DoRA adapts a pretrained DiT to the unified latent space without alpha-specific architectural changes.
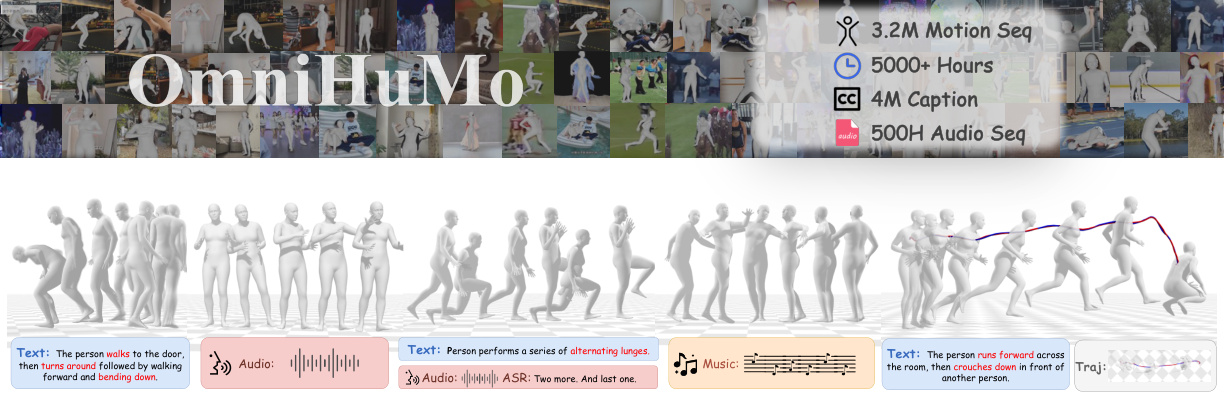
OmniHuMo, a large-scale multimodal motion dataset, and a unified framework combining a Residual FSQ motion tokenizer with masked modeling for any-modality conditional motion generation. Deployed in WeChat multimodal generation business.
Zhuo Li*, Mingshuang Luo*, Ruibing Hou†, Xin Zhao, Hao Liu, Hong Chang, Zimo Liu, Chen Li
* equal contribution · † corresponding author
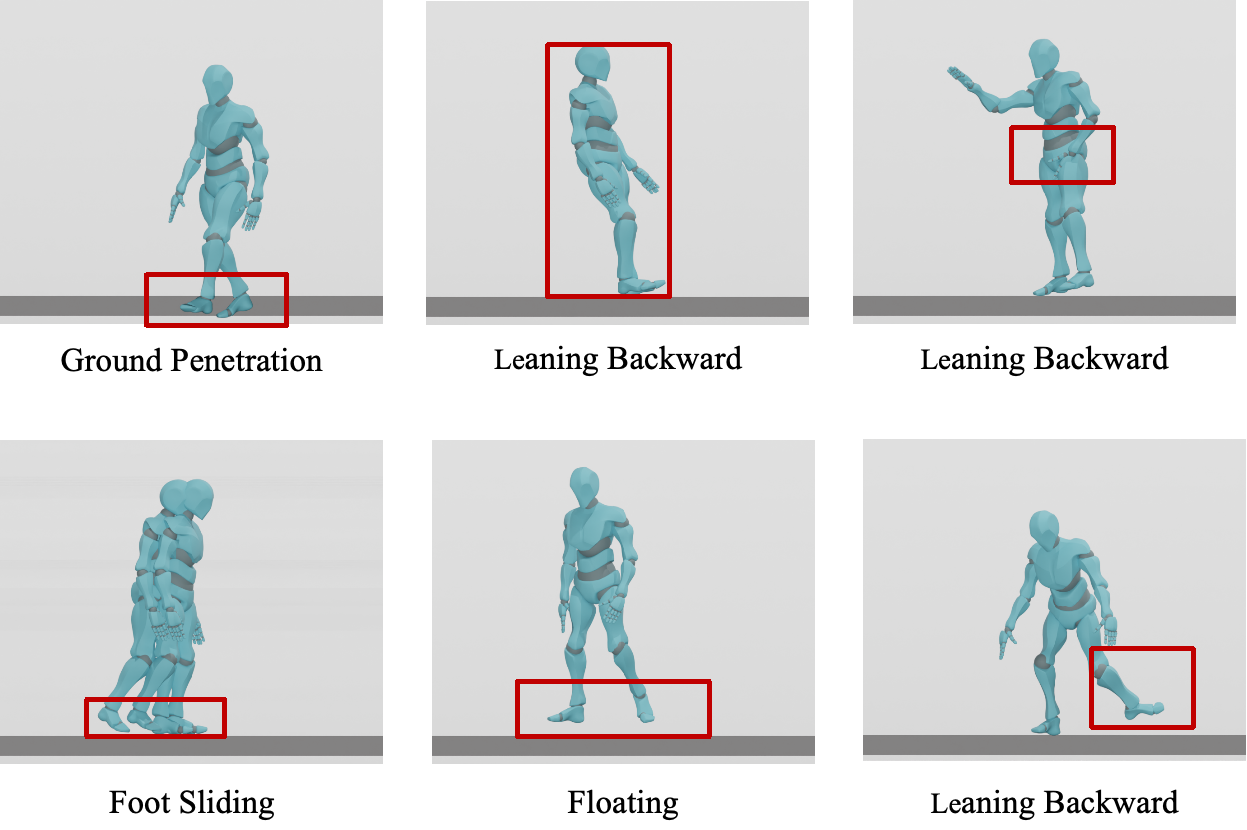
A motion-free physics optimization framework that refines generated human motion for improved physical plausibility, without relying on costly real-world motion data.
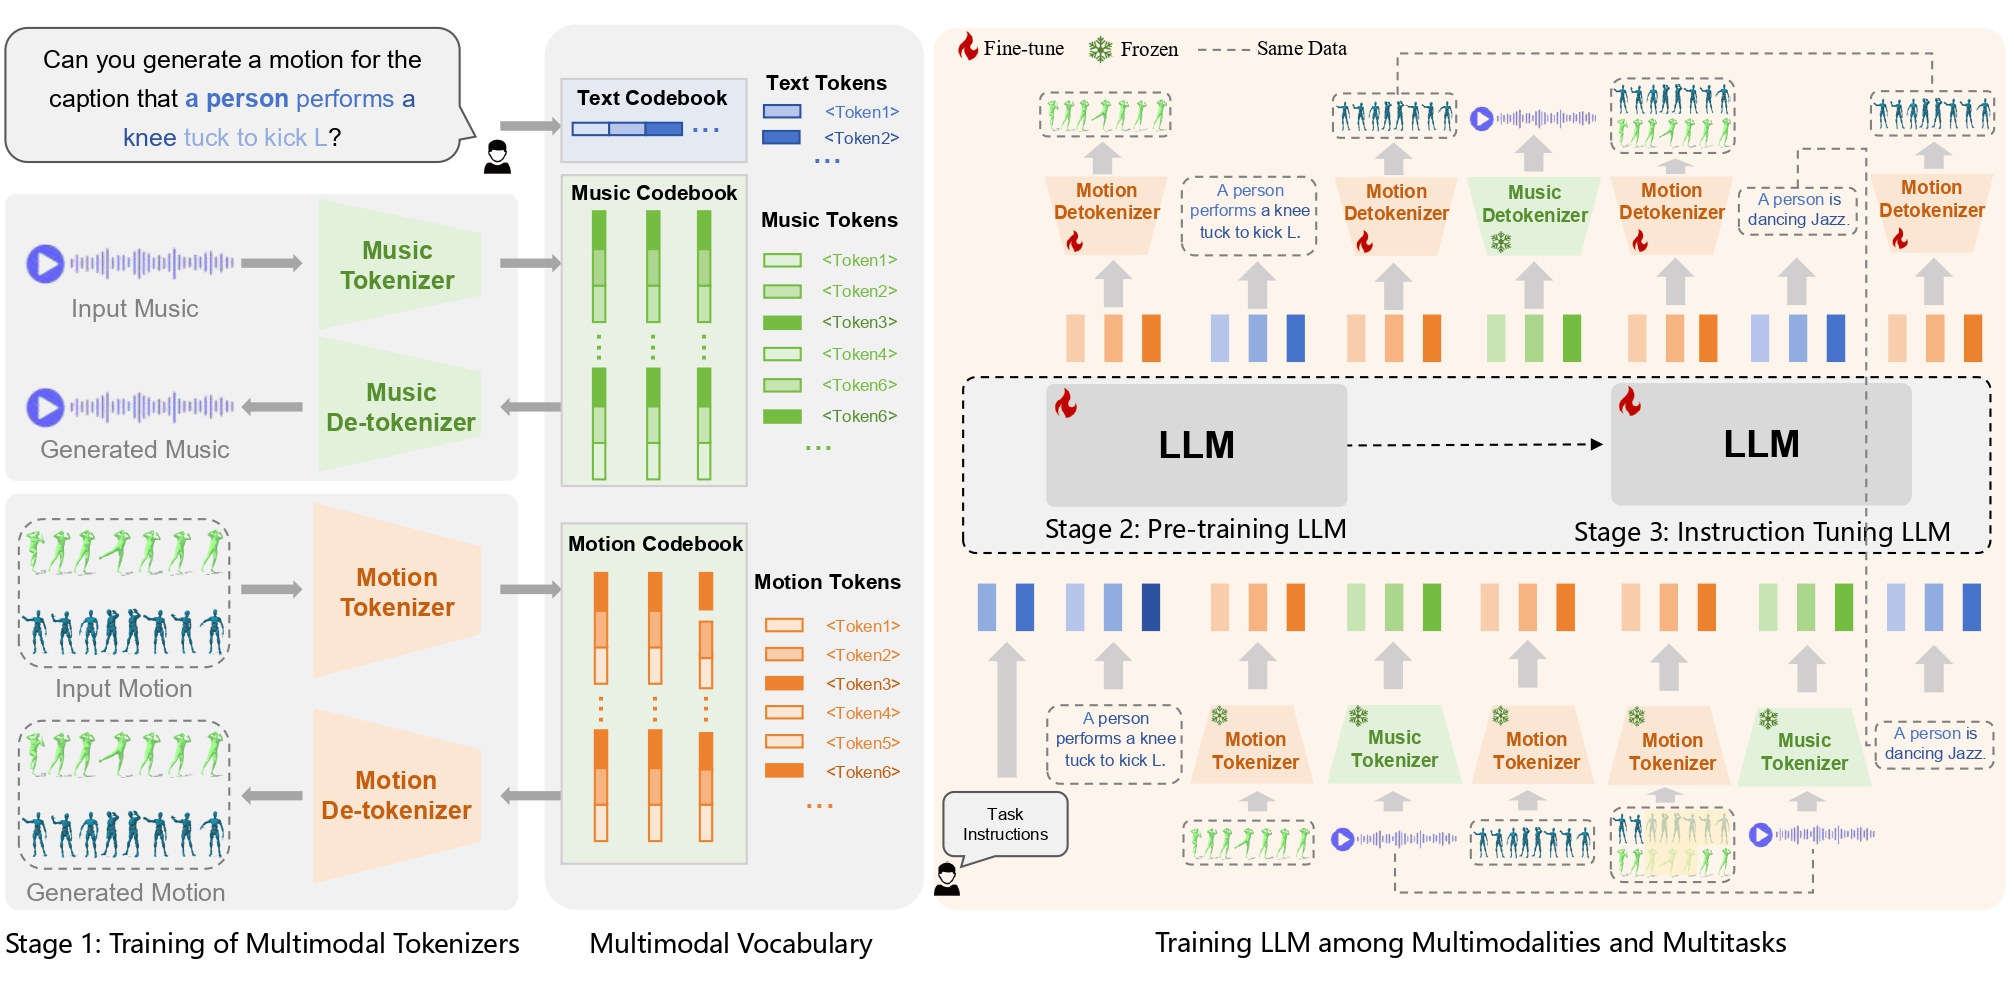
An autoregressive framework with a unified representation space for motion and music, integrating motion comprehension and generation across multiple tasks.